

Products » Dedicated GPU
Dedicated NVIDIA GPU to run AI in a Data Center in Brazil
Get the world's best GPUs as a service (IaaS) on robust infrastructure that keeps your AI operations reliable, secure and scalable.
100% of the GPU dedicated to your workload,
exclusive performance with no shared resources
High-performance compute power, bandwidth and graphics acceleration, backed by Brazil's largest Dedicated Server and Private Cloud company.


Thousands of cores in parallel
CPUs process tasks in sequence, while GPUs run thousands of operations at once. That is what makes it feasible to train models and run inference at scale.
Scalable and 100% dedicated to your project
With options from 16GB (T10) to high-capacity configurations, you choose VRAM based on your model size and run LLMs without splitting the workload or losing consistency.
Your GPU never waits for data
Integration with very high-IOPS disks keeps data flowing to the GPUs continuously, eliminating any read bottleneck.
Why choose EVEO Dedicated GPU
Powerful, fully isolated infrastructure for your business to train models and process data with security and stability.
Accelerated infrastructure for operations that demand predictability
No exchange rate swings, hourly billing or surprise charges: a fixed monthly cost in Brazilian reais with 100% dedicated hardware in Tier III Data Centers.
Freedom to choose the best GPUs on the market
From VDI on T10 to inference at scale on L4 and LLM training on HGX clusters with B300, EVEO sizes the right model for your project.
Your data kept secure on infrastructure in Brazil
Tier III Data Centers on Brazilian soil, minimal latency and a Portuguese-speaking technical team, 24x7. All from the country's largest dedicated server operation.


Infrastructure as a service that
prepares companies to lead the market with us
Thousands of companies have chosen to transform
their results with EVEO

Frequently asked questions about
Dedicated GPU
What is a GPU and what is it used for?

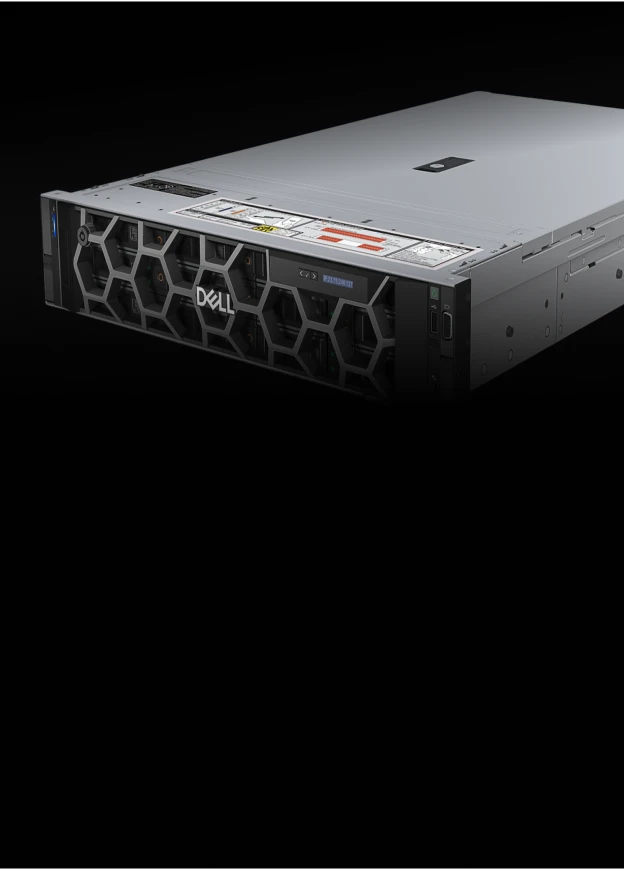
A GPU server is a server equipped with one or more graphics cards to accelerate parallel processing. It is used to train and run artificial intelligence models, perform LLM inference, 3D rendering, data analytics and VDI. With EVEO's dedicated GPU, the entire graphics card is reserved for your company, inside a complete server (CPU, memory and NVMe storage).
What projects is EVEO's dedicated GPU suited for?
EVEO's dedicated GPU is suited for companies that run intensive workloads and need stable performance, without competing for resources with other customers. The main projects are:
- Training and operating artificial intelligence and machine learning models, including LLM inference.
- Data analytics and big data processing.
- Professional 3D rendering and high-performance computing (HPC).
- Virtualization of engineering or architecture workstations (VDI).
Monthly dedicated GPU or hourly cloud GPU: which is the better deal?
In hyperscale public clouds, graphics resources usually run on fluctuating or shared demand, which exposes your operation to resource contention with other users and to operational instability. EVEO removes that friction by delivering full isolation. Your company is not affected by performance swings caused by others and has continuous availability to run complex models without interruptions or hardware surprises. We also replace complex traffic calculators with predictable corporate billing.
How much does a dedicated GPU server cost?
Your company gets a stable billing model suited to the budget realities of the Brazilian market. Unlike international providers that bill in foreign currency and are subject to daily exchange rate swings, EVEO contracts have fixed prices in Brazilian reais. We do not charge surprise fees on internal data transfer or traffic, which gives you real predictability and financial security when planning your business.
Is traffic unlimited?
Yes. Traffic is unlimited, with no charge for the volume transferred and no data egress fees. The network port speed depends on the plan you contract and is confirmed in the proposal.
Which NVIDIA GPU models are available in the infrastructure?
We work with a curated portfolio of latest-generation NVIDIA hardware to serve different stages of technology maturity:
- NVIDIA Tesla T10: optimized for robust graphics virtualization and stable VDI infrastructure.
- NVIDIA RTX PRO 4500 Server Edition: Built for professional AI workloads, computer graphics and high-performance processing.
- NVIDIA RTX PRO 6000 Server Edition: ideal for advanced AI, computer graphics and high-performance workloads.
- NVIDIA H200: latest-generation compute capacity, with large memory capacity and massive throughput for the most demanding workloads.
- NVIDIA HGX B300: designed for large-scale AI training and inference, with high-performance processing.
What is the difference between dedicated, shared and integrated GPUs?
In personal computers, a dedicated graphics card is one with its own chip and memory, while an integrated one sits inside the processor and shares system memory. In servers, "dedicated" means something else: the GPU belongs exclusively to a single customer. With a shared GPU, the card is split among several users and performance fluctuates with how others use it. With EVEO's dedicated GPU, cores, VRAM and bandwidth belong only to your company, making the whole operation more stable and predictable.
What is the difference between a CPU and a GPU?
A GPU (Graphics Processing Unit) is the processor on a graphics card. A CPU has a few cores, optimized to run tasks in sequence. A GPU has thousands of cores working in parallel, which makes it much faster at massive, repetitive calculations such as training AI models, rendering 3D images and processing large volumes of data. In a GPU server, the two work together: the CPU coordinates the system and the GPU accelerates the heavy workloads.
What is the availability SLA for Dedicated GPU?
Can I use more than one graphics card in the same server?
Yes. The number of cards depends on the chosen model and the server chassis. In multi-GPU configurations, such as H200 with NVLink and the HGX cluster with 8 B300 GPUs, the cards communicate over NVLink, a high-speed interconnect built for AI and different from SLI, which was designed for gaming. Our technical team sizes the configuration together with your team.
Which operating system and drivers come preinstalled?
Is the GPU for inference or only for training?
Can I run open-source LLMs in a private environment?
Yes. At EVEO, you host models such as Llama, DeepSeek, Qwen or Mistral in your own environment, without sending data to third-party APIs. It is an option for companies that want to use generative AI with sensitive data while keeping the information in Brazil and under their own team's control.
Can I start small and scale up later?
How does data storage for model training work?
The GPU server can be combined with local NVMe storage, for data that needs fast reads, and with EVEO's Object Storage, for larger dataset volumes. The architecture is defined together with your team based on data volume and access frequency.
Where are EVEO's GPU servers located?
The GPU servers are hosted in Tier III Data Centers in Cotia, Osasco, Curitiba, Fortaleza and Miami. Training and inference data stays on Brazilian soil, under Brazilian law. This makes compliance with the LGPD (Brazil's General Data Protection Law) easier and reduces latency for users in Brazil.
How soon is the GPU available after signing up?
Will I have full control over the environment? How does installing drivers and frameworks (such as CUDA, PyTorch or TensorFlow) work?
Set up your processing infrastructure
for high performance
Select the configuration that best fits your workload, taking into account data volume, concurrent task execution and the application's technical requirements.